Easy Timed Practice
Run a 30-minute self-guided design session for a news aggregator. Build ingestion, deduplication, and a paginated topic feed, then respond to changing conditions.
Run a 30-minute self-guided design session for a news aggregator. Build ingestion, deduplication, and a paginated topic feed, then respond to changing conditions.
This is a timed, self-guided mock interview. No live interviewer, automated evaluator, or AI feedback is connected. Use the on-page timer or your own timer, speak your decisions aloud, and save your draft before reviewing the model.
Scenario and constraints
- 10,000 publishers; five-minute ordinary freshness target.
- 5,000 peak feed reads/s.
- Publisher requests vary from 200 ms to 30 seconds.
- Only permitted metadata and links are collected in this exercise.
Your deliverables
- Minutes 0–5: agree on freshness, source policy, and feed behavior.
- Minutes 5–12: model article identity, revisions, and cursor pagination.
- Minutes 12–22: draw per-source scheduling and a replayable feed projection.
- Minutes 22–30: handle a slow source and a bad ranking deployment; recap.
Reason about this sequence
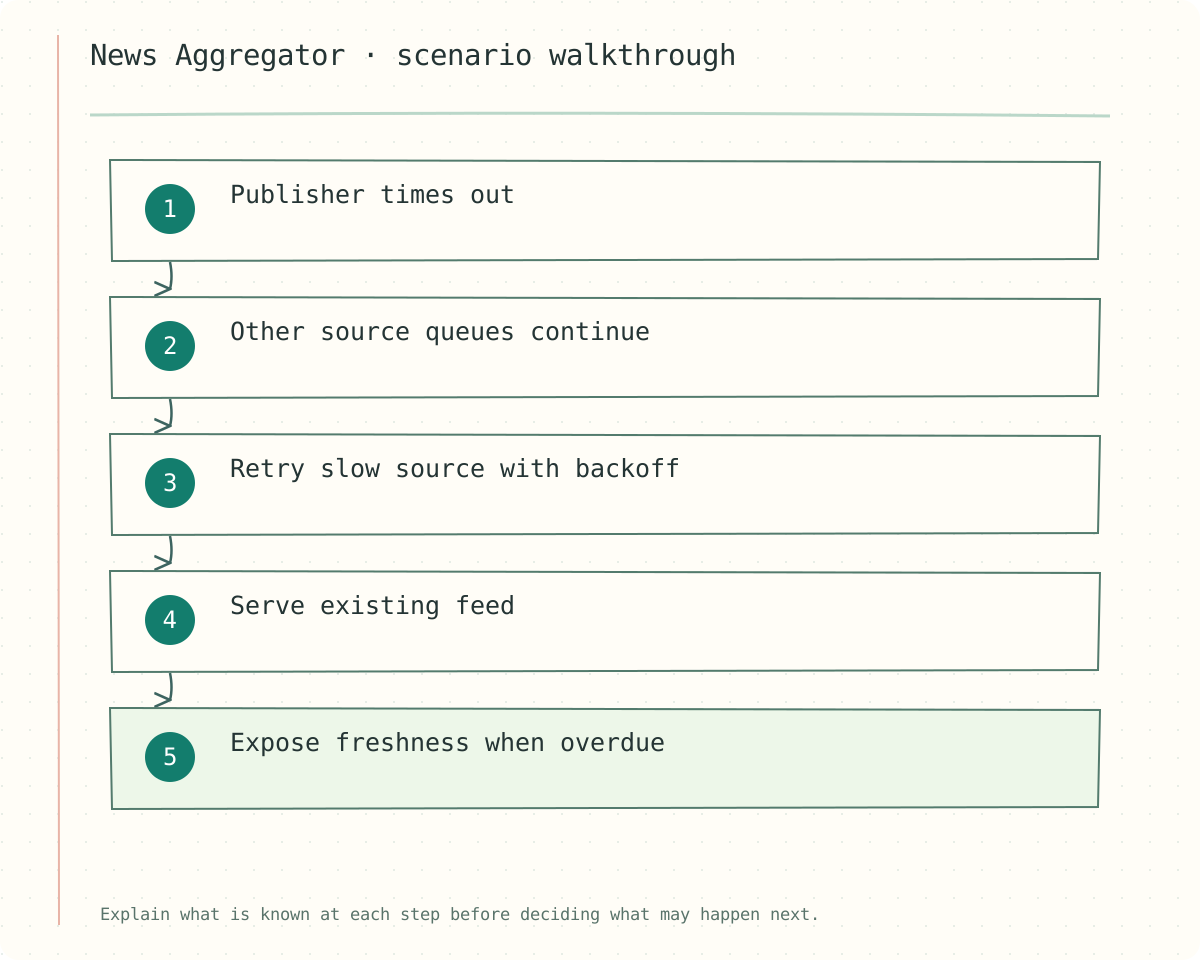
Figure — Publisher times out → Other source queues continue → Retry slow source with backoff → Serve existing feed → Expose freshness when overdue
For every step, annotate what is durable, what the caller knows, and which identity survives a retry. Identify the point where two concurrent actors could disagree. Do not assume a timeout means failure or a cache value grants ownership.
Interviewer follow-ups
- At minute 12, one publisher starts timing out.
- At minute 20, ranking accidentally promotes duplicate stories.
- At minute 25, a publisher removes an article.
Answer each follow-up using the same design first. If it breaks, change the smallest boundary that repairs the invariant and explain the new cost. Show whether the change adds latency, storage, coordination, or operational work.
Staged hints
Hint 1 — reveal
Answer: Hint 1 — Separate durable article facts from ranking output. Recovery should rebuild a view without re-fetching every publisher.
Hint 2 — reveal
Answer: Hint 2 — Fetchers submit normalized title, canonical URL, publisher identity, publication time, and retrieval time. URL canonicalization helps but is not perfect: tracking parameters may be removable while meaningful query parameters are not. Keep source identity and revision history. Content fingerprints can identify likely duplicates, but editorially distinct updates may need to remain separate.
Hint 3 — reveal
Answer: Hint 3 — A bug ranks every article from one source first. Because ranking is a projection, rebuild it from stored article facts under a new version. Compare diversity, duplicate rate, freshness, and latency before switching. Do not delete the previous projection until rollback is safe. If the source withdraws content, prioritize removal over ordinary ranking updates.
Evidence-based self-review
- Slow sources cannot block unrelated ingestion.
- Deduplication preserves meaningful article revisions.
- The feed projection can be rebuilt and rolled back.
- Freshness and removal behavior are measurable.
Score each item 0 if absent, 1 if named without an enforceable mechanism, or 2 if the mechanism and a failure are explained. Record evidence from your own diagram beside the score. Then choose one weak decision, revise it, and repeat the relevant follow-up. This rubric is a learning tool, not a hiring forecast.
Explain how to recover from a bad ranking deployment without fetching every source again.
Your design draft
Clarify assumptions, explain your approach, and test the difficult cases. Save your draft, then compare it with the study notes.
Self-review checklist
Self-guided practice. Automated AI feedback and code execution are not connected.