Web Crawler
A crawler is a scheduler with a fetch-and-discover loop.
Interview scope and guarantees
Accept seed URLs, fetch permitted pages, discover links, deduplicate work, and revisit changed pages. Define crawl scope, robots policy and retention. Fetch success is separate from parsing success; every stage needs bounded resources.
Capacity worksheet
Assume 100 million pages/day at 100 KB compressed each: 10 TB/day and about 1,157 fetches/s average. With 500 ms mean service time, Little’s Law gives about 579 concurrent fetches before headroom. Per-host politeness can dominate aggregate capacity, so unlimited workers do not imply faster completion.
Concrete API contract
POST /crawls {seeds,scope,maxPages} -> {crawlId}
GET /crawls/{id} -> {counts,state}
Internal claim {host,leaseGeneration} -> due URL
Internal complete {url,attempt,status,contentHash}
Data model and access paths
urls(normalized_url_hash PK,url,host,state,next_fetch_at,content_hash)
frontier(host,due_at,url_id,priority)
fetch_attempts(url_id,attempt,generation,status,object_key)
host_policy(host,robots_version,next_allowed_at)
Evolve a solution and explain each change
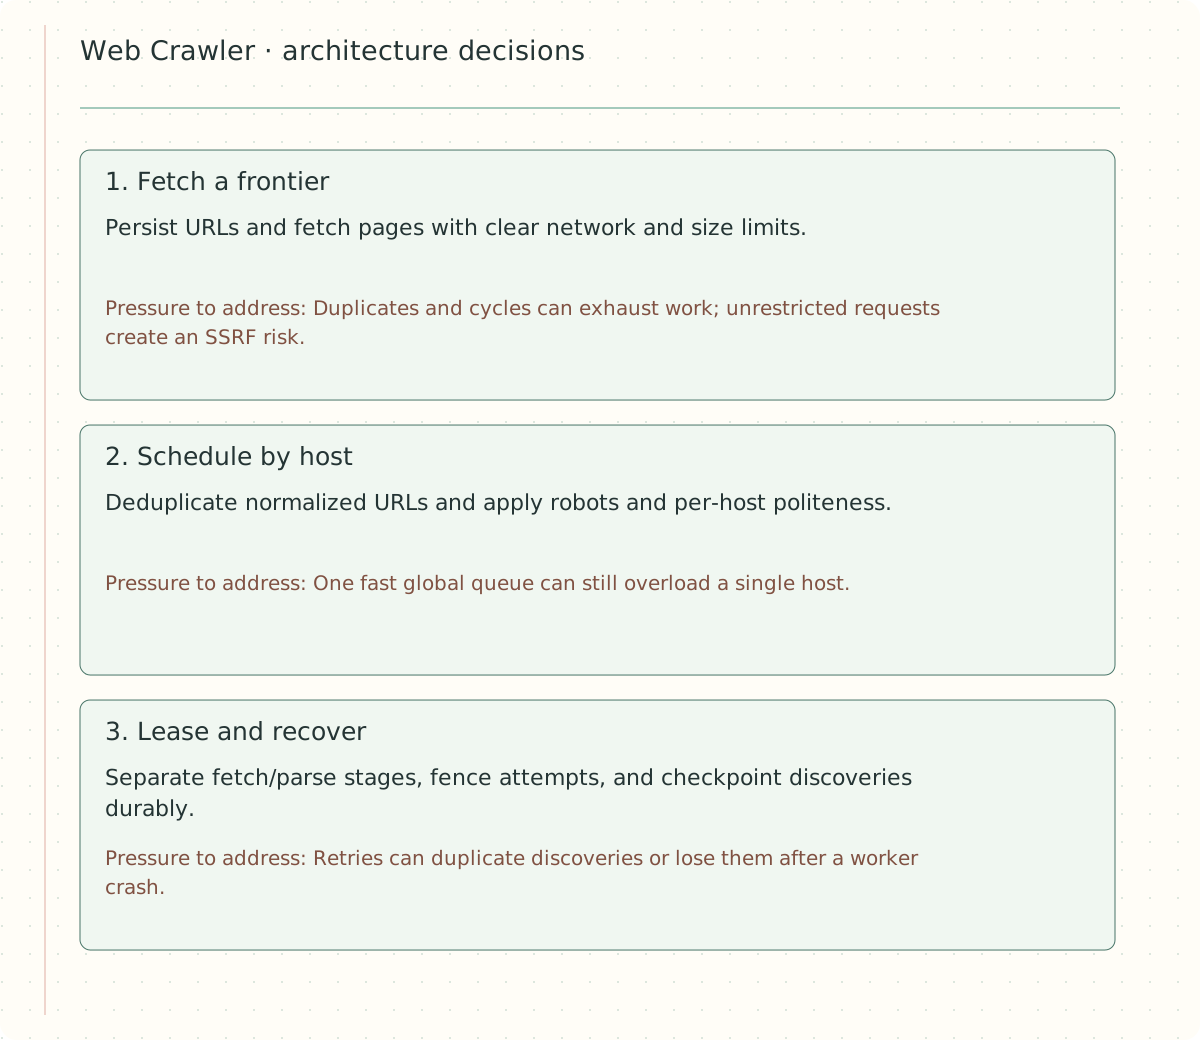
Figure — Three architecture decisions for Web Crawler, including the pressure each introduces.
Step 1: Fetch a frontier
Persist URLs and fetch pages with clear network and size limits. Duplicates and cycles can exhaust work; unrestricted requests create an SSRF risk.
Step 2: Schedule by host
Deduplicate normalized URLs and apply robots and per-host politeness. One fast global queue can still overload a single host.
Step 3: Lease and recover
Separate fetch/parse stages, fence attempts, and checkpoint discoveries durably. Retries can duplicate discoveries or lose them after a worker crash.
Responsibility overview
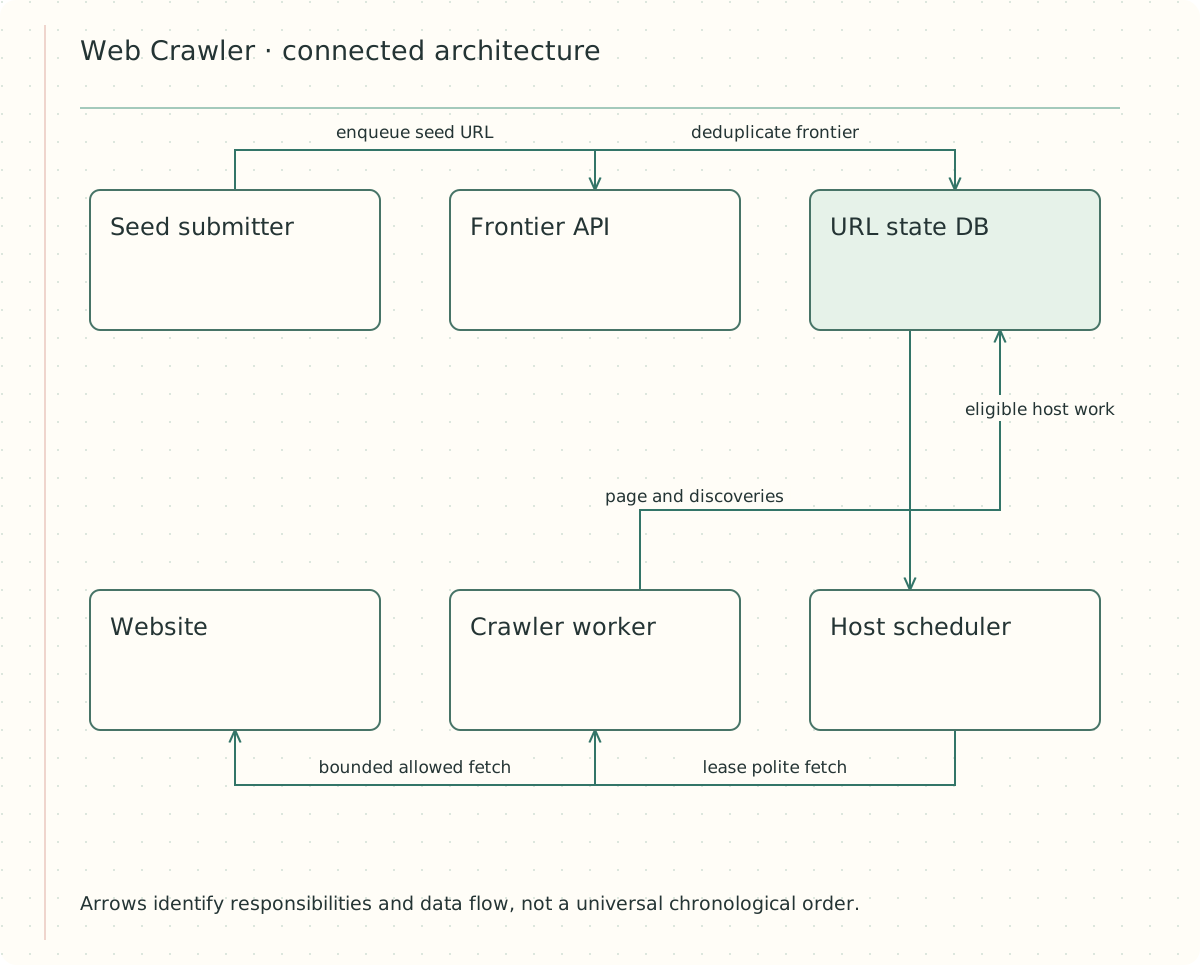
Figure — Connected responsibilities for Web Crawler. Trace the authoritative and derived paths separately.
Worked end-to-end scenario
A page links to itself and to the same article through two URL spellings. Normalize under a documented rule, then atomically insert the frontier key if absent. Worker W leases a URL, checks robots and the host’s next eligible time, and fetches with redirect, payload, and address restrictions. It persists the result before enqueuing discovered links. If W crashes after storing the page, retrying should not erase its discoveries; use an outbox or replayable parse stage. A robots response failure needs an explicit conservative policy. DNS and redirect checks must also prevent a public URL from reaching protected internal addresses.
Why these access paths matter
Frontier entries include normalized URL, host, next fetch time, attempt, and state. Index ready jobs by eligible time and keep host rate state separately. Content hashes can reduce duplicate storage but should not suppress required link processing silently. A Bloom filter can reject definite absence efficiently; possible presence requires exact lookup when skipping a fresh URL is unacceptable.
Build the baseline first
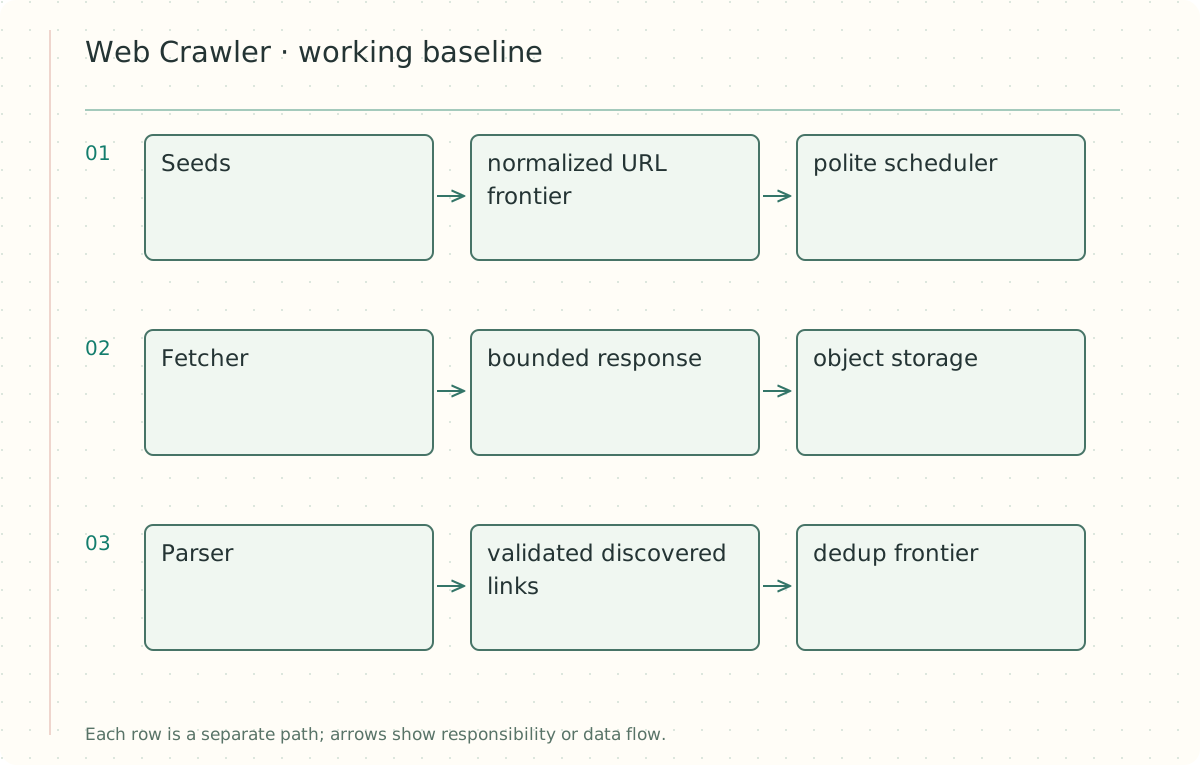
- Seeds → normalized URL frontier → polite scheduler.
- Fetcher → bounded response → object storage.
- Parser → validated discovered links → dedup frontier.
Evolve the design under load
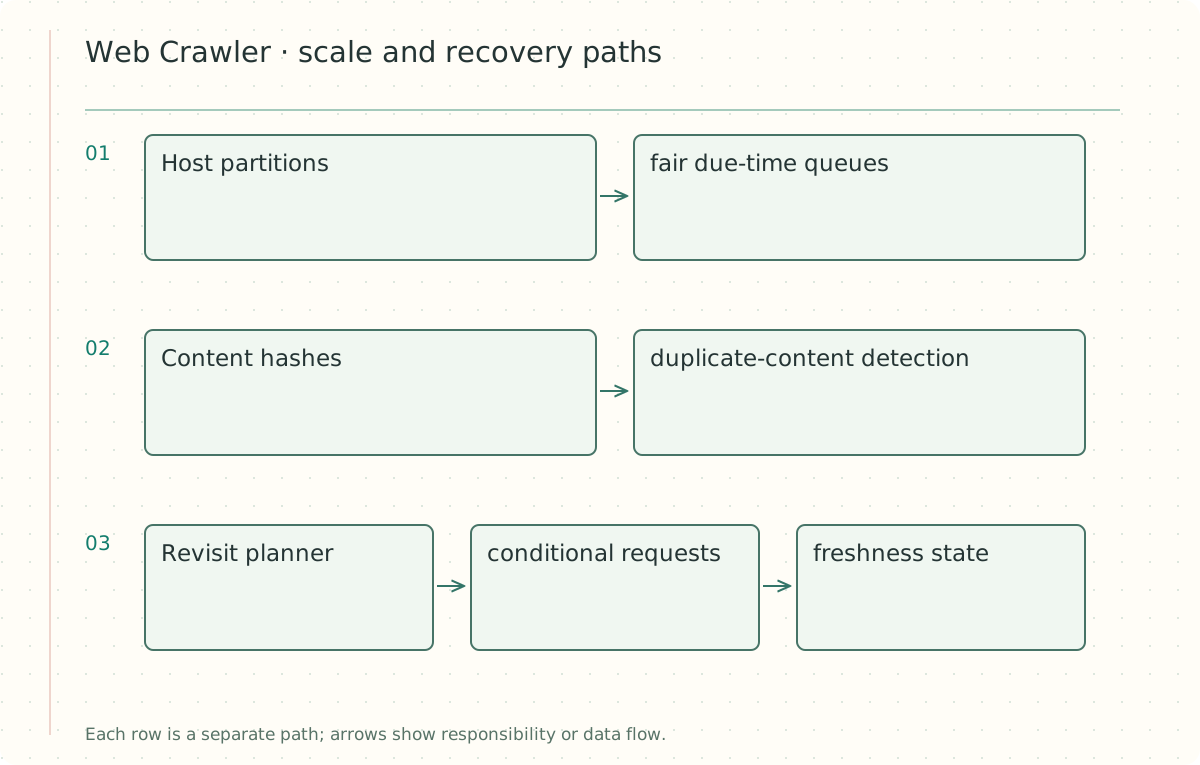
- Host partitions → fair due-time queues.
- Content hashes → duplicate-content detection.
- Revisit planner → conditional requests → freshness state.
Defend the hardest decision
URL normalization must preserve semantic differences: blindly dropping query parameters can merge distinct pages. Keep exact deduplication for required correctness and use a Bloom filter only as an optional fast membership hint. Schedule by host so one domain cannot occupy every worker. A durable per-host next-allowed time coordinates polite access across workers; a separate connection cap limits slow hosts.
Failure and recovery analysis
A URL resolves to a private network address after initial validation. Revalidate destinations on connection and after redirects to resist SSRF and DNS rebinding. Bound redirect count, decompressed size, total time and parser resource use. On worker death, reclaim the lease with a newer generation, and ignore stale completion writes.
Security and privacy boundary
Respect robots and site access policy, identify the crawler, and avoid fetching authenticated or private resources without permission.
Interview follow-ups with reasoning
Question: How do you avoid crawler traps?
Show answer and explanation
Answer: Cap depth and URL variations and monitor repeated low-value patterns.
Question: How do you refresh efficiently?
Show answer and explanation
Answer: Use last-modified or entity tags when supported and prioritize by measured change rate.
Question: How do you recover the frontier?
Show answer and explanation
Answer: Persist scheduling decisions and rebuild derived priority indexes from URL state.
Operate and verify the design
Per-host fetch rate, oldest frontier age, parser failures and duplicate discoveries.
Introduce a calendar trap and a slow host; verify unrelated hosts continue within their budgets.
A second scenario to test transfer
One host exposes a calendar with links to every future month. A naive crawler continuously discovers new URLs and starves other sites. A host-level discovery budget and pattern-aware scope stop the expansion. Another host returns 429; its next fetch is deferred while unrelated eligible hosts continue. Fair scheduling matters more than adding download workers.
Why can a global FIFO waste capacity even when thousands of URLs remain?
Show answer and explanation
Answer: The next URLs may belong to hosts that are delayed, throttled, or already at their concurrency limit. Eligible-host scheduling can make progress on other hosts without violating per-host policy.
Compare alternatives
| Concern | Mechanism | Trade-off |
|---|---|---|
| Politeness | Per-host scheduling | Lower peak speed per host |
| Infinite discovery | Budgets and scope rules | May miss low-priority pages |
| Duplicate content | Fingerprints | Hash/storage cost |
| Freshness | Adaptive recrawl | Scheduling complexity |
A design-changing exercise
A fetch succeeds but the worker crashes before discovered links are enqueued. How is coverage recovered?
Show answer and explanation
Answer: Persist parse/discovery intent with the fetched result or keep a replayable parse job. Acknowledging the frontier entry alone can lose traversal work.
Design workshop: schedule eligible hosts, not just URLs
Core scope is allowed HTTP(S) fetch, parse, discover and recrawl; login/cookie scraping is excluded. Choose one in-flight fetch per host and an illustrative one-second host interval. These are crawler policy assumptions, not permissions granted by robots.txt. Per-host budgets and overall page/byte limits remain mandatory for bounded work.
Store urls(normalized_url UNIQUE,host,state,next_fetch_at,attempt_generation), hosts(host PK,next_eligible_at,inflight,robots_version), fetches(url,generation,object_key,checksum,status), and parse_jobs(fetch_id UNIQUE,state,version). Normalize fragments and host case, preserve meaningful query parameters and path case, and document redirect/canonical handling. A URL fingerprint is an accelerator; exact normalized identity decides duplicates.
while capacity_available():
    host = claim_earliest_eligible_host(now)  # fenced lease/transaction
    if not host: break
    url = claim_due_url(host)
    if not url:
        release_host(host); continue
    reserve_host_slot_and_next_time(host, now + politeness_interval)
    enqueue_fetch(url, host.lease_generation)
Host claiming atomically verifies inflight capacity and next eligible time. A min-heap over eligible hosts avoids a FIFO blocked behind one throttled domain. Persist next times/leases so restarts do not unleash all URLs at once. On 429 honor applicable Retry-After and back off the host; a trap creating infinite calendar pages hits per-host discovery and depth/URL budgets.
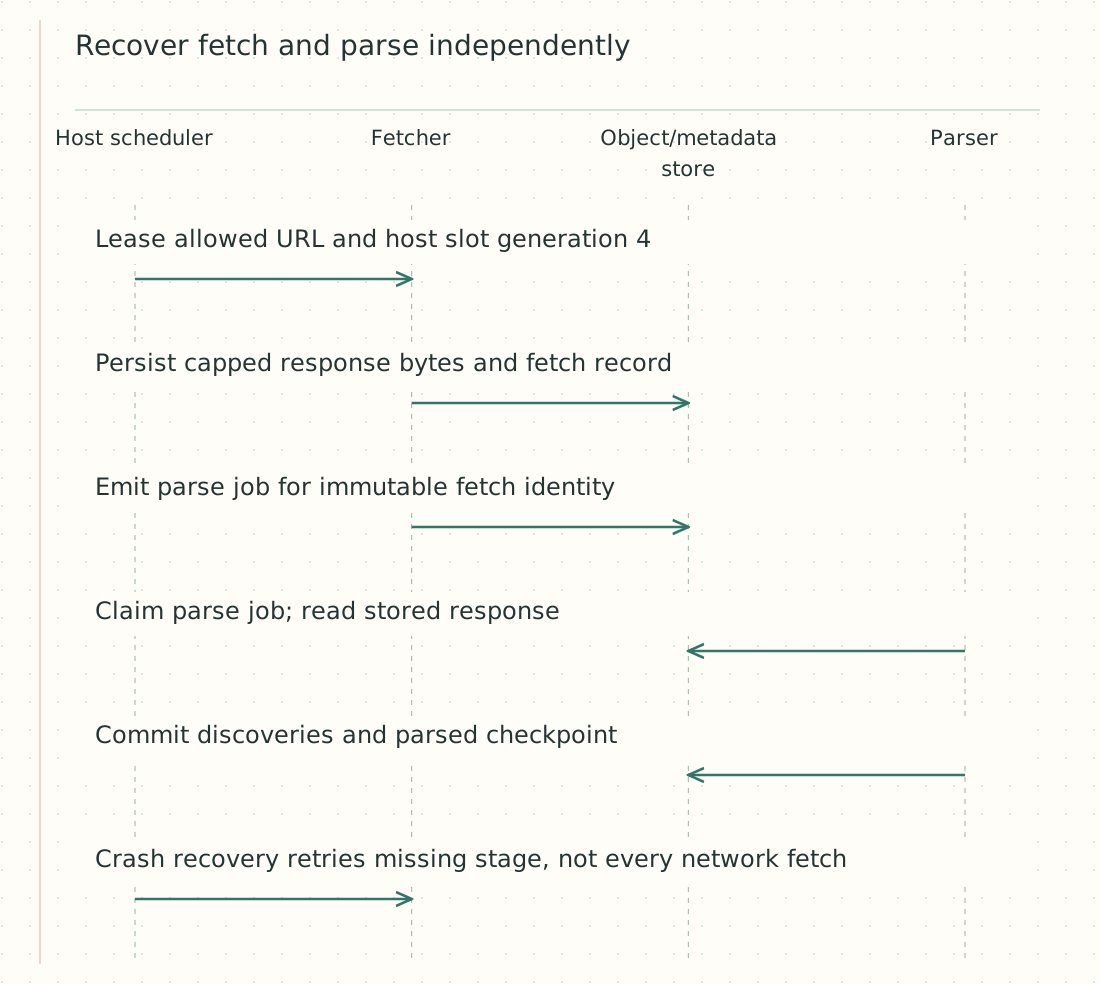
Figure — Recover fetch and parse independently.
Robots handling follows the protocol distinction: a 4xx unavailable robots resource may permit access under the RFC, while server/network errors make it unreachable and require initial complete disallow; cached rules and prolonged-unreachable treatment have documented boundaries. This crawler chooses the conservative policy of delaying on network/5xx failures and refreshing cached rules normally within 24 hours. Follow redirects under a bounded policy and evaluate rules for the applicable origin. Robots is not authentication or a blanket legal access grant.
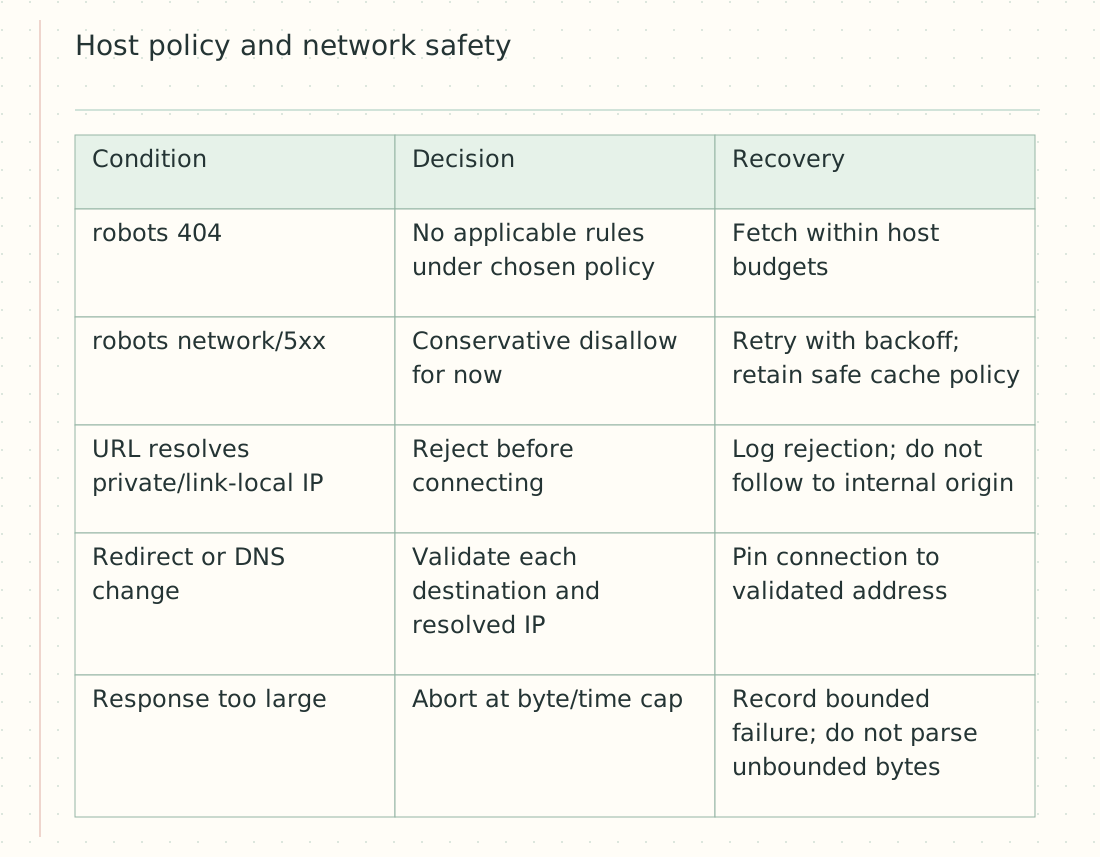
Figure — Host policy and network safety.
For SSRF defense, resolve, validate every returned candidate address and connect to a validated address without an independent uncontrolled re-resolution. Validate redirects and preserve TLS hostname checks. Restrict egress at the network layer as well; URL parsing alone is insufficient. Decompression has an expanded-byte cap so a tiny compressed response cannot exhaust memory.
A Bloom hint for n=10 million URLs at p=0.01 needs approximately −n ln(p)/(ln2)^2 =95.9 million bits, about 12 MB, with about seven hashes. A positive can be false, so skipping it without an exact check can miss new pages. At 1,000 fetches/s averaging 200 KB, ingress is 200 MB/s; provision parsing and storage throughput separately. Recrawl prioritizes change likelihood and desired freshness with per-host fairness.
Exercise: A worker persisted bytes but crashed before parsing. Should recovery refetch immediately?
Show answer and explanation
Answer: If the durable fetch record validates the object and parse identity, resume parsing that object. Refetch only if missing/corrupt or recrawl policy requires a newer version. This separates duplicate network cost from idempotent discoveries.
Robots Exclusion Protocol, RFC 9309 is the primary source for robots status handling.
Technical references
Why can a global FIFO waste capacity even when thousands of URLs remain?
Your design draft
Clarify assumptions, explain your approach, and test the difficult cases. Save your draft, then compare it with the study notes.
Self-review checklist
Self-guided practice. Automated AI feedback and code execution are not connected.