Sharding
Sharding divides data across independent storage owners so one machine does not need to hold or process everything.
Sharding divides data across independent storage owners so one machine does not need to hold or process everything. It changes the routing and transaction model, not merely the number of replicas. A good shard key makes common requests local and spreads both bytes and work. Those two goals can conflict when customers or keys are highly uneven.
Learning goals
Partition keys; hash and range layouts; tenant skew; secondary lookups; cross-shard queries; resharding; routing metadata; online migration.
The mechanism at a glance
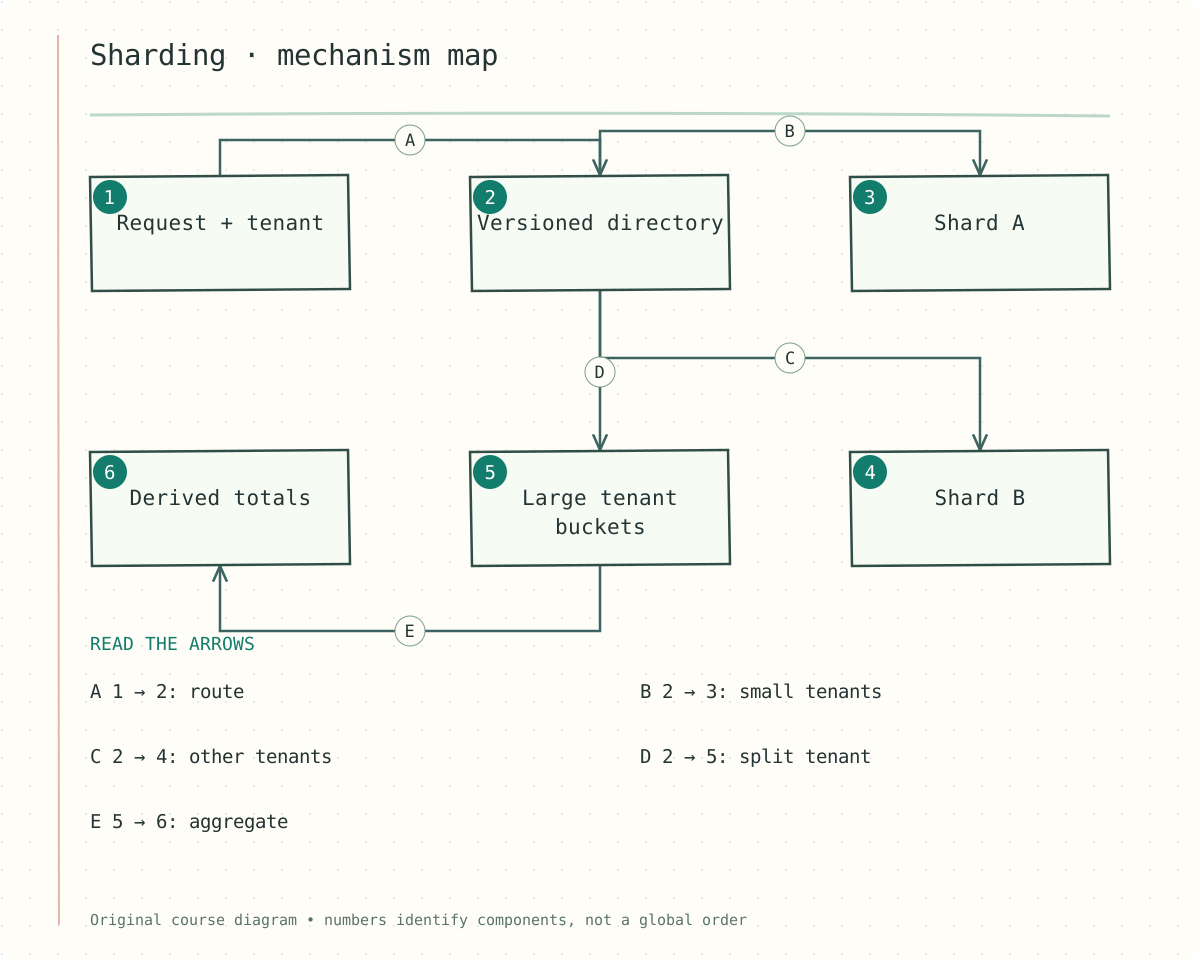
Figure — Request + tenant → Versioned directory (route); Versioned directory → Shard A (small tenants); Versioned directory → Shard B (other tenants); Versioned directory → Large tenant buckets (split tenant); Large tenant buckets → Derived totals (aggregate)
The numbered components identify responsibilities. Follow the labeled arrows rather than treating the numbers as a global execution order. The scenario later in this lesson shows one concrete sequence.
Step-by-step reasoning
1. Choose the routing key from queries
A tenant key keeps tenant-scoped queries local and simplifies ownership. A hash of object ID often distributes many independent objects more evenly but turns tenant-wide queries into fan-out. Range partitioning supports ordered scans but a growing timestamp range can concentrate writes on the newest partition. Evaluate both request distribution and data volume.
2. Separate replication from partitioning
Replicas contain copies of the same partition for availability or reads. Shards contain different subsets. Three replicas of a hot shard do not automatically divide its writes among three independent owners. Document how a router finds a shard and how it learns a new placement after migration.
3. Make hot tenants splittable
Hashing a single large tenant ID sends every request for that tenant to the same location. Add a subpartition dimension, such as a stable object bucket, when one tenant exceeds a shard budget. This introduces fan-out for tenant-wide operations. Isolate exceptionally large tenants when that is operationally simpler than forcing every tenant through the same scheme.
4. Plan migration before the emergency
An online split needs a copy phase, catch-up of changes, validation, and a fenced routing cutover. Decide which owner may accept writes at every point. A directory version or routing epoch helps reject stale routes. Keep a rollback plan and do not delete the old copy until correctness and traffic have been verified.
Contracts and state
The following sketch makes the decision boundary concrete. Field names and capacity assumptions are illustrative; adapt them to the stated product contract.
Routing example
small tenant: directory[tenant] -> shard A
large tenant: directory[tenant] -> bucketed layout v2
bucket = hash(object_id) mod 16
route = directory[tenant, bucket, routing_epoch]

Cross-bucket totals are derived, not single-row reads.
Worked example
A delivery service stores attempts by tenant and month. This bounds historical partitions, but one customer generates half the current month’s traffic. Creating more empty shards does not move that hot partition. Split that tenant by delivery ID bucket, keep attempts for one delivery together, and build aggregate counts asynchronously. The design now has an explicit cost: a tenant-wide export reads several buckets.
Failure walkthrough
A stale router writes to the old owner after cutover. Copying data alone does not prevent divergence. The old owner must reject or forward writes using the migration epoch, while the new owner accepts the current epoch. Validate counts and sampled checksums, track replication or catch-up lag, and test interrupted migration before using this during an outage.
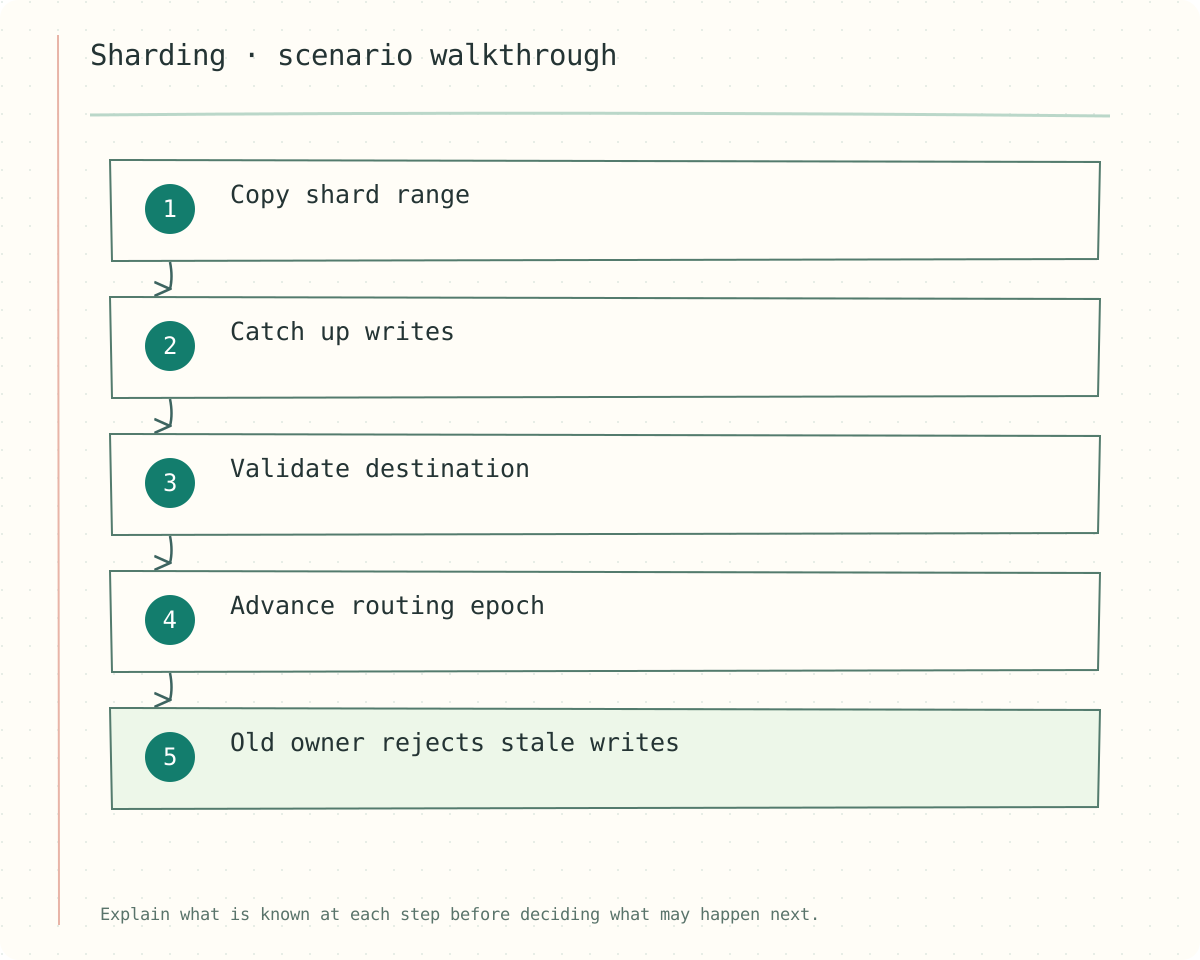
Figure — Copy shard range → Catch up writes → Validate destination → Advance routing epoch → Old owner rejects stale writes
Decisions and trade-offs
| Key | Strength | Weakness |
|---|---|---|
| Tenant | Local customer operations | Large-customer skew |
| Object hash | Even independent object placement | Cross-object scans fan out |
| Time range | Retention and range scans | Newest range can be hot |
Check your understanding
A hash function is perfectly uniform over tenant IDs. Why can one shard still receive most writes?
Show answer and explanation
Answer: Uniform placement of IDs does not imply uniform request rates. A single extremely active tenant remains one key. Subpartition its workload or give it dedicated capacity, accepting the resulting query and migration costs.
Transfer to a new scenario
Partition delivery attempts by tenant and time, then split a tenant too large for one partition.
Why does hashing a single huge tenant ID still leave one hot shard?
Continue the connection
Study Consistent Hashing and explain which guarantee from this lesson carries into that topic.
Move a range without losing ownership
Assume a tenant-partitioned service has one tenant responsible for 40% of writes. Adding more shards for other tenants does not relieve it. Split that tenant by a stable secondary dimension such as account ID or time bucket, then state which queries now fan out and which transactions cross boundaries.
A safe migration needs a source of truth for ownership. Copy a snapshot, stream subsequent changes, catch up to a known position, then switch a routing epoch. During transition, define which owner accepts writes and how stale routers are redirected. Dual writes without reconciliation can diverge when one succeeds and the other fails.
Track per-shard bytes, requests, latency and hot keys. Equal key counts do not imply equal load. Rebalancing itself consumes I/O, network and cache capacity; throttle it so a repair does not become an outage. Keep a rollback strategy consistent with writes accepted after cutover.
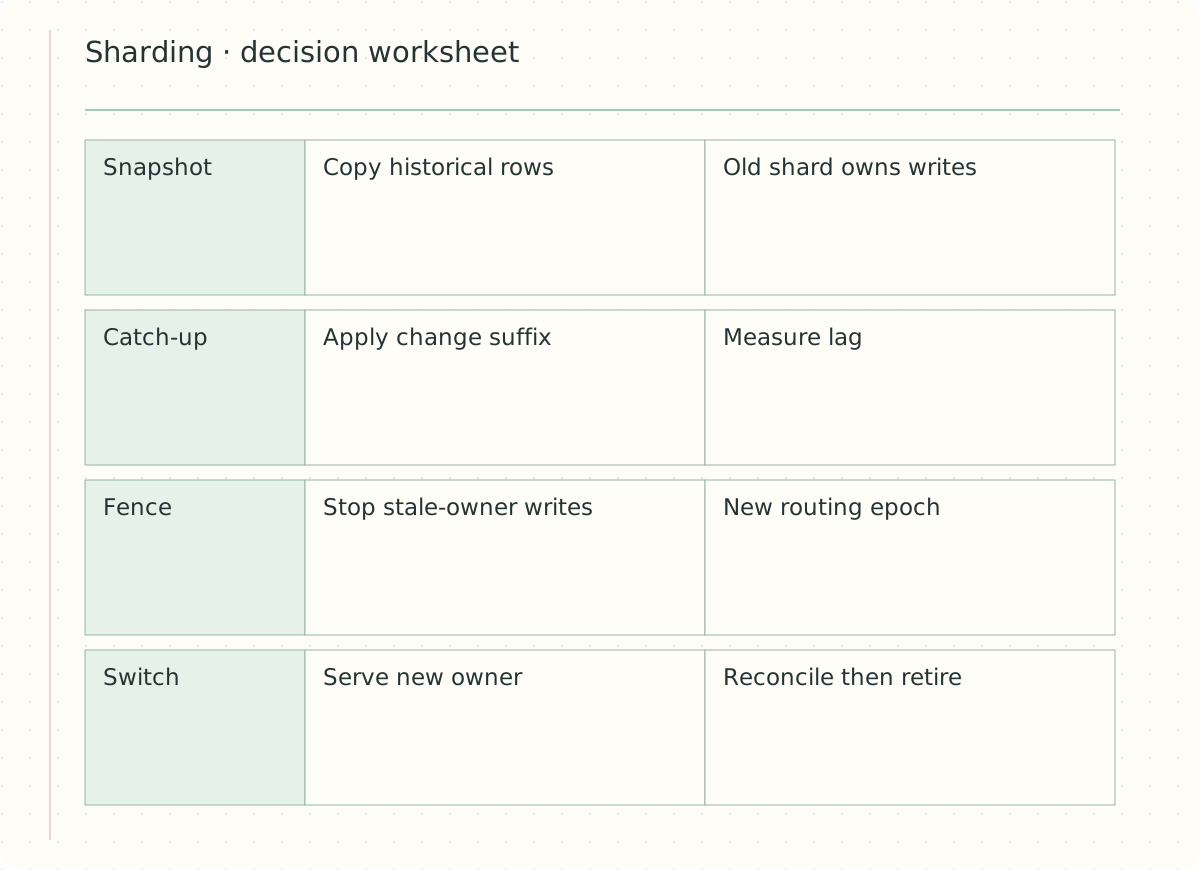
Figure — A decision worksheet for Sharding: read the mechanism and its guarantee together.
Operational sketch
route(tenant,subkey) -> {shard,epoch}
write(expected_epoch, key, value)
old owner rejects or redirects stale epoch
migration: snapshot -> catch-up -> fence -> switch
A tempting mistake
A queue between shards does not make a cross-shard invariant atomic. Decide whether to colocate the invariant, coordinate a transaction, or implement a business workflow with compensation.
Transfer exercise
What is missing from “copy the rows and update DNS”?
Show answer and explanation
Answer: Concurrent writes, routing caches, ownership fencing, catch-up position and rollback. DNS does not establish a single authoritative writer for each key.